

How long to run an A/B test: from sample size to whole weeks
How long to run an A/B test: divide the required sample by eligible daily traffic, round up to whole weeks, and plan for novelty effects and sales.
By Sergey BruhPublished 9 min read
How long to run an A/B test: divide the required sample by eligible daily traffic, round up to whole weeks, and plan for novelty effects and sales.
By Sergey BruhPublished 9 min read
A free course for PMs and marketers: short lessons, real product data and exercises with instant feedback.
Start the free course10 min read
Peeking in A/B testing turned a 5% false-positive rate into 27.6% in 100,000 simulated tests. When to stop an A/B test, and how sequential testing helps.
9 min read
What minimum detectable effect (MDE) means, relative vs absolute, and how to set it from business value and your traffic. With a worked example.
10 min read
How to calculate sample size for an A/B test: the formula, a worked example, how statistical power and MDE change the number, and a free calculator.
To work out how long to run an A/B test, divide the total sample the test needs by the number of eligible users who enter it each day, then round the result up to whole weeks. Run it for at least two full weeks even when the maths says four days, and treat anything beyond about eight weeks as a sign that the test needs a different design.
CatChow, an online pet-food shop, wants to show a delivery estimate ("Arrives on Thursday") next to the buy button on product pages. Emily, the product manager, plans the test:
The sample size calculator returns 31,234 users per group, 62,468 in total. The post on A/B test sample size explains where that number comes from.
The shop gets about 8,000 visitors a day, but only 2,500 of them open a product page. So:
Rounded up to whole weeks, the test runs for 4 weeks (28 days). Friday is not happening.
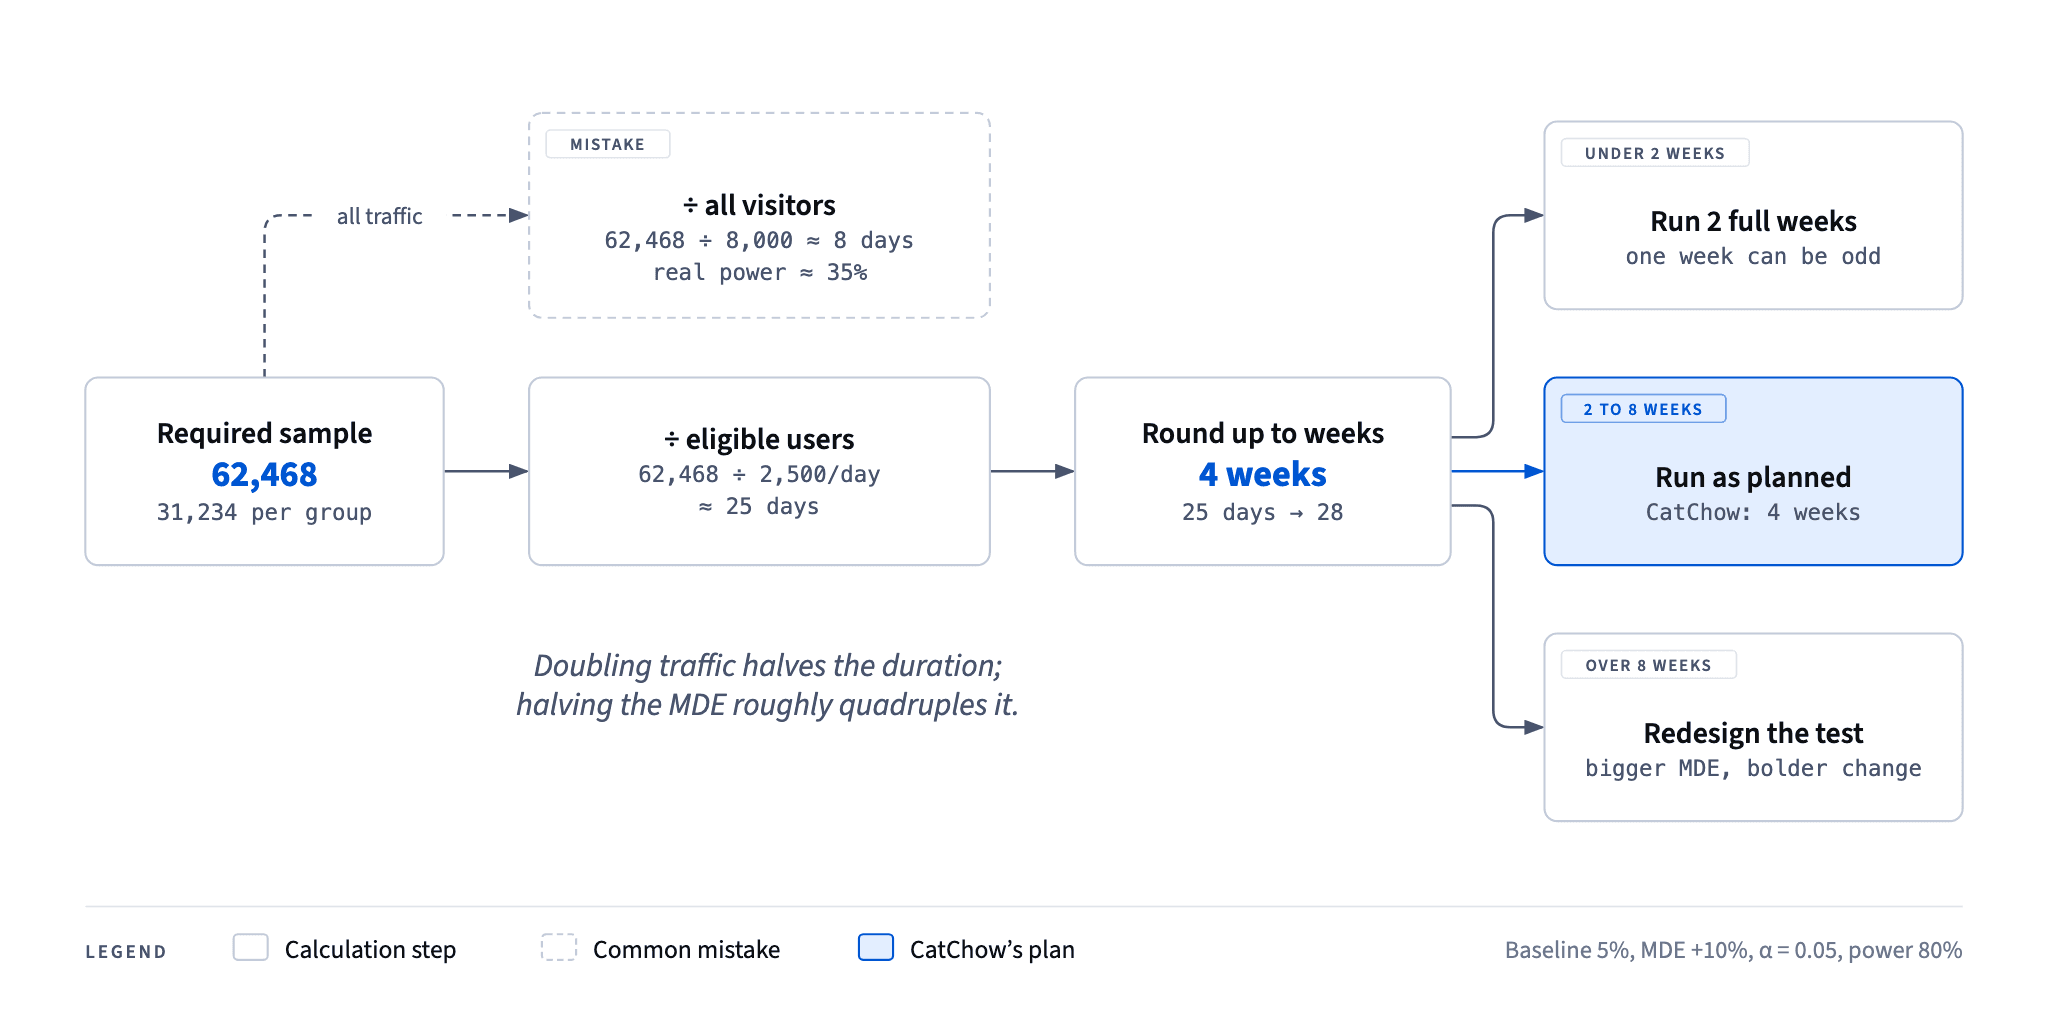
Eligible users are those who reach the tested page and can see the change. Had Emily divided by all 8,000 visitors, the plan would say 8 days. In 8 days only 20,000 people open a product page, 10,000 per group, and with that sample the chance of detecting a real 10% lift is about 35% instead of the planned 80%. The test would most likely come back "not significant", and a working idea would be shelved.
Take the traffic figure from ordinary recent weeks and count unique users, not sessions.
People shop differently on a Tuesday morning and on a Sunday evening. If a test launched on a Monday stopped on day 25, Monday to Thursday would be counted four times and Friday to Sunday only three. Whole weeks give every weekday the same weight.
The same test (baseline 5%, , power 80%) for different effects and traffic levels:
Doubling the traffic halves the duration, but halving the MDE roughly quadruples it.
If you start from a deadline, turn the question around. The MDE calculator shows that with 2,500 users a day CatChow can detect a lift of 13.5% in two weeks and 9.4% in four. Which effect is worth chasing is the topic of the post on the minimum detectable effect.
Minimum: one to two full business cycles. For most online shops the cycle is a week, so "1 week" in the table becomes two in practice. A single week can be an odd one (a holiday, a newsletter, an outage), and two weeks let you compare the first with the second. If your customers buy on a longer rhythm, such as a monthly order after payday, cover one full cycle of it.
Maximum: about six to eight weeks. Longer tests degrade:
If the plan says 14 weeks, don't wait it out. Accept a larger MDE, test a bolder change, or move to a metric with a higher baseline (add-to-cart instead of order).
A novelty effect is a lift that exists because the change is new: regular visitors notice the unfamiliar block, click it, and later lose interest. A primacy effect is the opposite: people used to the old version stumble at first, and the variant improves as they adapt.
To spot them, compare the first week with the later ones. Suppose Emily's test finished like this, with 8,750 users per group each week:
Weekly numbers are noisy: each weekly difference carries a margin of about ±0.7 percentage points, so the wobble between weeks 2 and 4 means little. A first week with a lift almost four times the last one's is a different matter. Weeks 2 to 4 together give +9.0%, a more honest estimate of what CatChow will keep.
A second check: split new and returning users. Newcomers have no old version to compare with, so a lift seen only among returning users is probably novelty.
Showing the variant to only 10% of users feels safer, but it is expensive. For the same test (5.0% to 5.5%, 2,500 eligible users a day):
The calculator assumes an even split; the other two rows apply the same formula to unequal groups. The smaller group limits the precision of the comparison: at 90/10 the variant still needs about 17,100 users, and at 250 a day that takes ten weeks. In total, a 90/10 split costs 2.7 times the traffic of an even one.
If the risk worries you, expose 10% of users for a day or two to catch bugs, then switch to 50/50 and count the test from that moment.
A test measures the effect on the people who were there while it ran. Black Friday visitors hunt for discounts and buy with a different urgency, so a lift measured that week may not hold in February.
Stopping the moment the primary metric looks significant is peeking, and it inflates false positives; the post on A/B test peeking explains why. Stopping because the variant hurts users is different, as long as the rule is written down before launch:
This is safe because an early stop for harm can only end in "don't ship", never in shipping a false winner.
Only to catch bugs. Three days cover only part of the weekly pattern, and the first days carry the strongest novelty effect. Run one full week at the very least, and two whenever you can.
Change the test, not the calendar: a larger MDE with a bolder change, a metric higher in the funnel, or a page with more traffic. If none of that works, decide without a test and say so openly.
Not quite. People who joined on the last day need as much time to decide as those who joined on the first. If most orders arrive within three days of the first visit, stop adding new users on day 28 and keep counting orders for three more days.
The free lesson Pitfalls: peeking, multiple testing, novelty effect works through peeking, multiple comparisons and the novelty effect on CatChow experiments, with quizzes and a practice task checked by AI. It is part of the free course Statistics for Product Managers and Marketers.