

Confidence interval in A/B tests: what it really tells you
What a 95% confidence interval tells you in an A/B test, how to read one that crosses zero, and why it beats a bare p-value for ship decisions.
By Sergey BruhPublished 9 min read
What a 95% confidence interval tells you in an A/B test, how to read one that crosses zero, and why it beats a bare p-value for ship decisions.
By Sergey BruhPublished 9 min read
A free course for PMs and marketers: short lessons, real product data and exercises with instant feedback.
Start the free course10 min read
Peeking in A/B testing turned a 5% false-positive rate into 27.6% in 100,000 simulated tests. When to stop an A/B test, and how sequential testing helps.
8 min read
P-value explained in plain words: the p-value meaning in an A/B test, what p < 0.05 says about statistical significance, and what it doesn't.
A confidence interval is the range of values for the true conversion rate, or for the true difference between two variants, that fits the data you collected. Your test measured a lift of 0.7 percentage points, but another sample of visitors would give a slightly different number. A 95% confidence interval replaces the single number with an honest range, such as "+0.13 to +1.27 percentage points". That range answers the three questions a ship/no-ship decision depends on: could the effect be zero, could it be negative, and is it large enough to pay for itself? A p-value answers only the first.
CatChow, an online pet-food shop, adds an estimated delivery date ("Arrives Thursday") to the product page. The estimate comes from a carrier's paid API, so the feature has a running cost. After two weeks:
The variant is ahead by 0.7 percentage points (pp), a 14% relative lift.
For a conversion rate measured on visitors, the standard error says how much the rate would bounce from sample to sample. The 95% interval is the rate plus or minus 1.96 standard errors:
The decision is about the gap between the variants, so this is the interval that matters. The two standard errors combine like the legs of a right triangle:
The margin of error is pp, so the 95% confidence interval for the lift is +0.13 to +1.27 pp. The two-proportion z-test on the same data gives ; the lesson on conversion rate tests walks through that calculation.
The tempting reading is "there is a 95% chance that the true lift is between 0.13 and 1.27 pp". That is the classic misreading. The true lift is unknown but fixed, and this particular interval either contains it or doesn't.
The 95% describes the method, not your interval. If CatChow could run the same test a hundred times and build an interval each time by the same recipe, about 95 of those intervals would capture the true lift and about 5 would miss it. You hold one of them and can't tell which kind it is.
A safe everyday version: "the data is compatible with a lift anywhere from 0.13 to 1.27 pp". Two practical consequences:
"" says that a gap this large would be rare if the delivery date did nothing (more on that in P-value explained). The interval shows three things at once:
The range also translates into business units. CatChow's product pages get about 50,000 visitors a month, so the interval means roughly 65 to 635 extra orders a month, with 350 as the single best estimate.
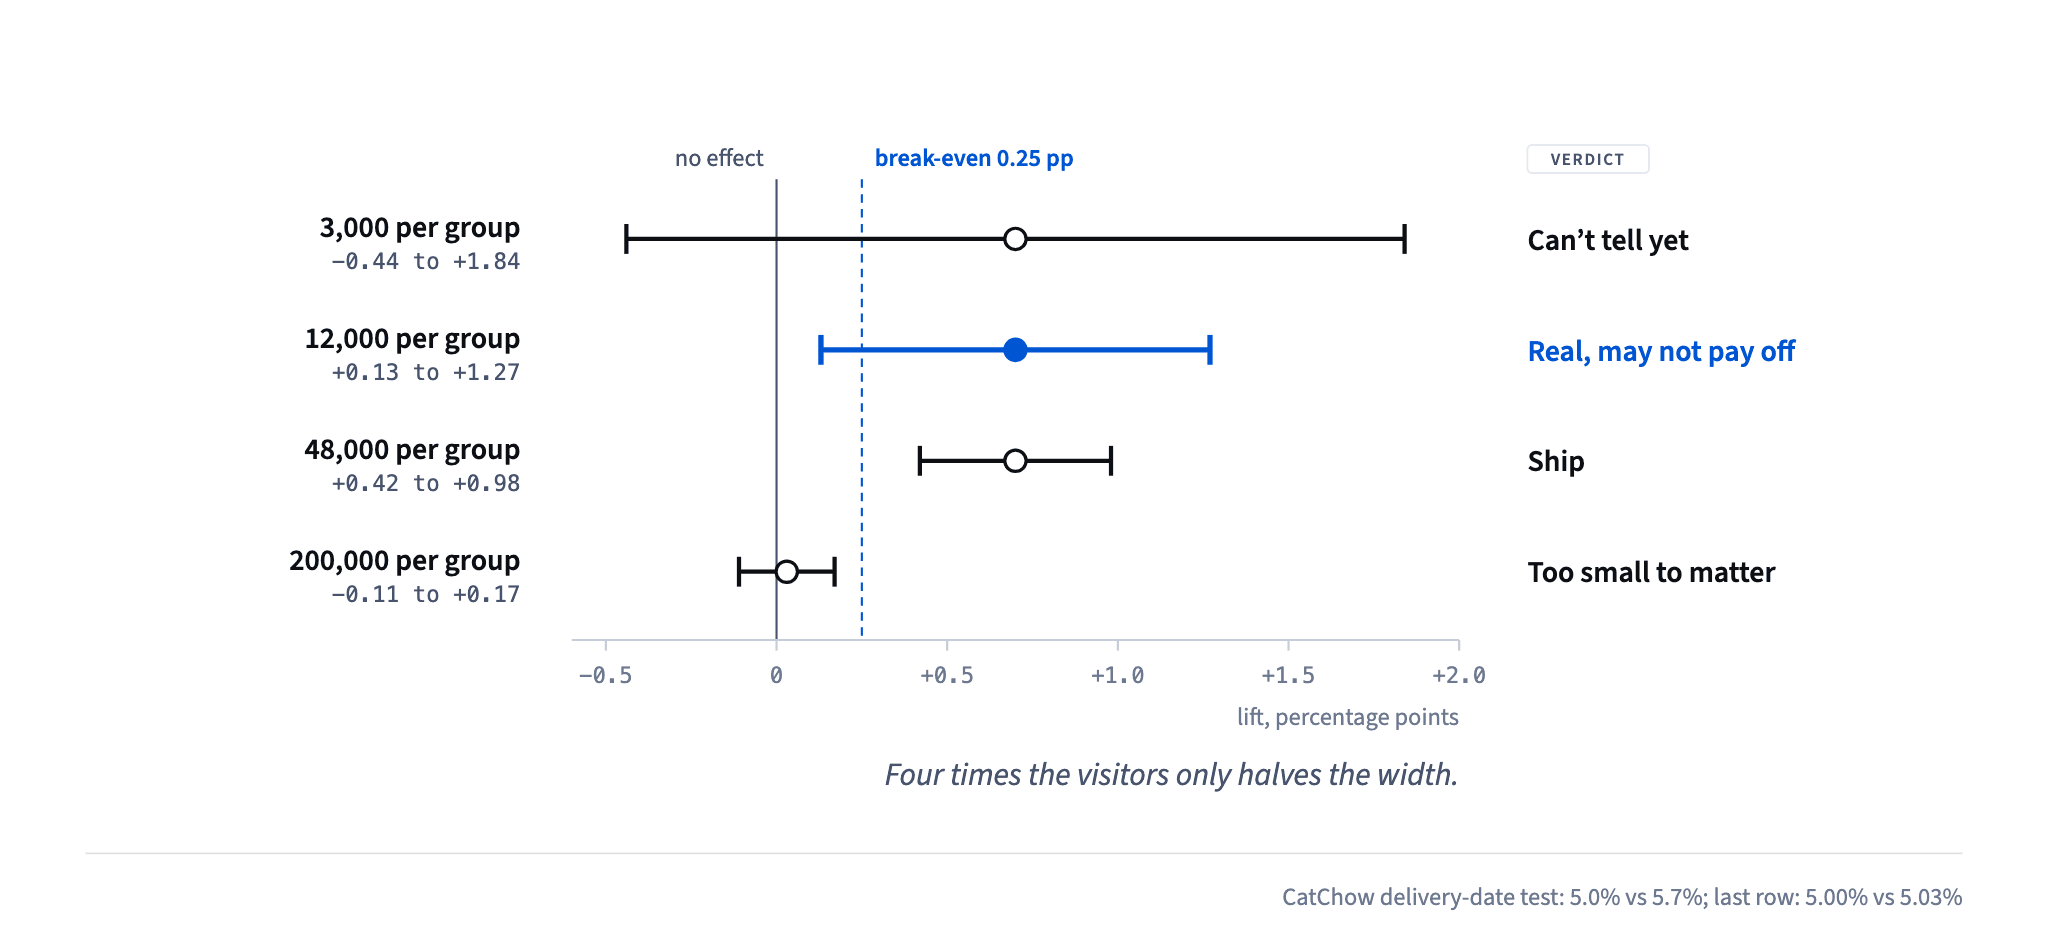
Here are the same observed rates, 5.0% and 5.7%, at three test sizes:
The sample size sits under a square root, so four times the visitors only halves the width. That is why precision is decided before launch, when you plan the sample size, not after the results arrive.
The confidence level changes the width too. At 90% the 12,000-visitor test gives +0.22 to +1.18 pp; at 99% it gives −0.05 to +1.45 pp. More confidence costs a wider interval, so pick the level before the test, not after you see the results.
Take the first row of the table: 3,000 visitors per group and an interval of −0.44 to +1.84 pp, with . The data is compatible with a small loss, with no effect and with a large gain. That is not "the delivery date doesn't work". It is "this test couldn't tell".
Now a different test: 200,000 visitors per group, 5.00% against 5.03%. The interval is −0.11 to +0.17 pp. It also crosses zero, but the message is the opposite: whatever the effect is, it is tiny.
A p-value calls both tests "not significant" (0.23 and 0.66). The intervals show that the first needs more data and the second is a clear answer.
Zero is rarely the line that matters for the business. The carrier's API costs CatChow 1,500 dollars a month, and an average order brings about 12 dollars of margin. Breaking even takes 125 extra orders a month, which at 50,000 visitors is a lift of 0.25 pp: the minimum effect worth shipping.
CatChow's +0.13 to +1.27 pp is the second row. At the low end the feature brings about 780 dollars of margin a month against 1,500 dollars of cost. At the point estimate it nets about 2,700 dollars a month. Values near the middle of an interval are better supported by the data than values at its edges, so shipping and re-checking after a quarter is a reasonable call. It is still a business call, and the interval is what makes it visible.
With three variants there are three pairs to compare and more chances for a false alarm. Our A/B/n test results calculator takes three to six variants and reports, for every pair, the difference, a Bonferroni-adjusted p-value and an adjusted interval for the difference.
Adjusted intervals are wider. With a third variant in the delivery date test, the interval for the same gap between B and A would be roughly +0.004 to +1.40 pp instead of +0.13 to +1.27 pp, and the adjusted p-value 0.048 instead of 0.016. The calculator uses a more accurate formula than the textbook one above (Newcombe's method, built on Wilson score intervals); at sample sizes like these the two agree to two decimals.
Judging by overlap. The intervals of the two variants overlap (4.61–5.39% and 5.29–6.11%), yet the interval for the difference excludes zero. Overlapping intervals are not a test. Look at the interval for the difference.
Reading it as a range of user behaviour. The interval does not say where 95% of visitors or days fall. It describes the uncertainty about one number, the true rate.
Mixing up percent and percentage points. +0.13 to +1.27 pp is an absolute lift. Relative to the 5.0% baseline it is roughly +3% to +25%. Always say which one you mean.
Trusting the interval of a test you peeked at. If you stop the moment the interval clears zero, it no longer has 95% coverage.
The delivery date raised conversion from 5.0% to 5.7%: a lift of 0.7 pp (95% CI +0.13 to +1.27 pp), which is roughly 65 to 635 extra orders a month against a break-even of 125.
The pattern: what changed, the point estimate, the interval, the same range in business units and the threshold it is compared with.
For a conversion rate on visitors: . In the delivery date test, the control's 5% on 12,000 visitors gives 4.61% to 5.39%.
No. The true value is fixed, so a given interval either contains it or doesn't. The 95% is the long-run success rate of the method: about 95 of 100 intervals built this way capture the true value.
The data is compatible with no effect, so the result is not statistically significant at that level. It does not prove the effect is zero: a wide interval means the test was too small, a narrow one means any effect is small.
95% is the standard and matches a significance level of 0.05. Use 99% when a wrong launch is expensive to undo, and 90% for cheap, reversible changes. Choose before the test starts.
Usually the sample is small for the effect you are chasing. Halving the width takes four times the traffic.
The free lesson Confidence intervals builds an interval step by step on CatChow's order data, with quizzes on the misreadings above and a practice task checked by AI. It is part of the free course Statistics for Product Managers and Marketers.