

Theory
Simple linear regression
Simple linear regression: predicting one metric from another with a line of best fit, and checking the fit with R squared.
~11 min read · 11 exercises · 250 points
Before you start
What does one more dollar buy?
Yesterday you found that CatChow's ad spend and orders move closely together. Today the CFO wants something more concrete from the product team: how many extra orders does one more dollar of ad spend buy?
The correlation can't answer that. In this lesson you'll fit a straight line through the same ten weeks with simple linear regression, use it to make a prediction, and check how well it fits.
From correlation to a line you can use
Correlation answers "how tightly do two metrics move together?" with one unit-free number. It can't answer the question a budget owner actually asks: "how many more orders does one more dollar bring?"
Chart data
| Ad spend, USD | Orders from ads |
|---|---|
| 200 | 20 |
| 300 | 23 |
| 350 | 30 |
| 400 | 28 |
| 450 | 36 |
Show 5 more rows
| 500 | 33 |
| 550 | 42 |
| 600 | 38 |
| 650 | 48 |
| 700 | 44 |
Simple linear regression answers it with an equation:
ŷ = b0 + b1 × x
- x is the independent variable (predictor), here weekly ad spend;
- ŷ (y-hat) is the predicted value of the dependent variable (outcome), here orders from ads;
- b1 is the slope: how much ŷ changes for each one-unit step in x;
- b0 is the intercept: the value of ŷ where the line crosses x = 0.
"Simple" means one predictor; the next lesson adds more.
Two things regression doesn't add. It doesn't prove causation: the line describes the pattern in the data, and a confounder can create a slope just as easily as an r. And it doesn't make the data less noisy: dots still scatter around the line. What you gain is a number you can plan with, for spend levels the data actually covers.
- Doŷ = 8.85 + 0.0539 × spend: plug in $500, get about 35.8 orders.
- Don't“We fitted a regression, so now we know ads cause orders.”
A fitted line is still a description of the data.
Least squares and residuals
Many lines pass "through the middle" of a cloud of dots. The least squares method picks one by a precise rule.
For every dot, measure the residual: the vertical gap between the actual value and the line's prediction, e = y − ŷ. A positive residual means the dot sits above the line (the line under-predicted); a negative one means it sits below. Then square each residual and add them up. The least-squares line is the one with the smallest possible sum of squared residuals.
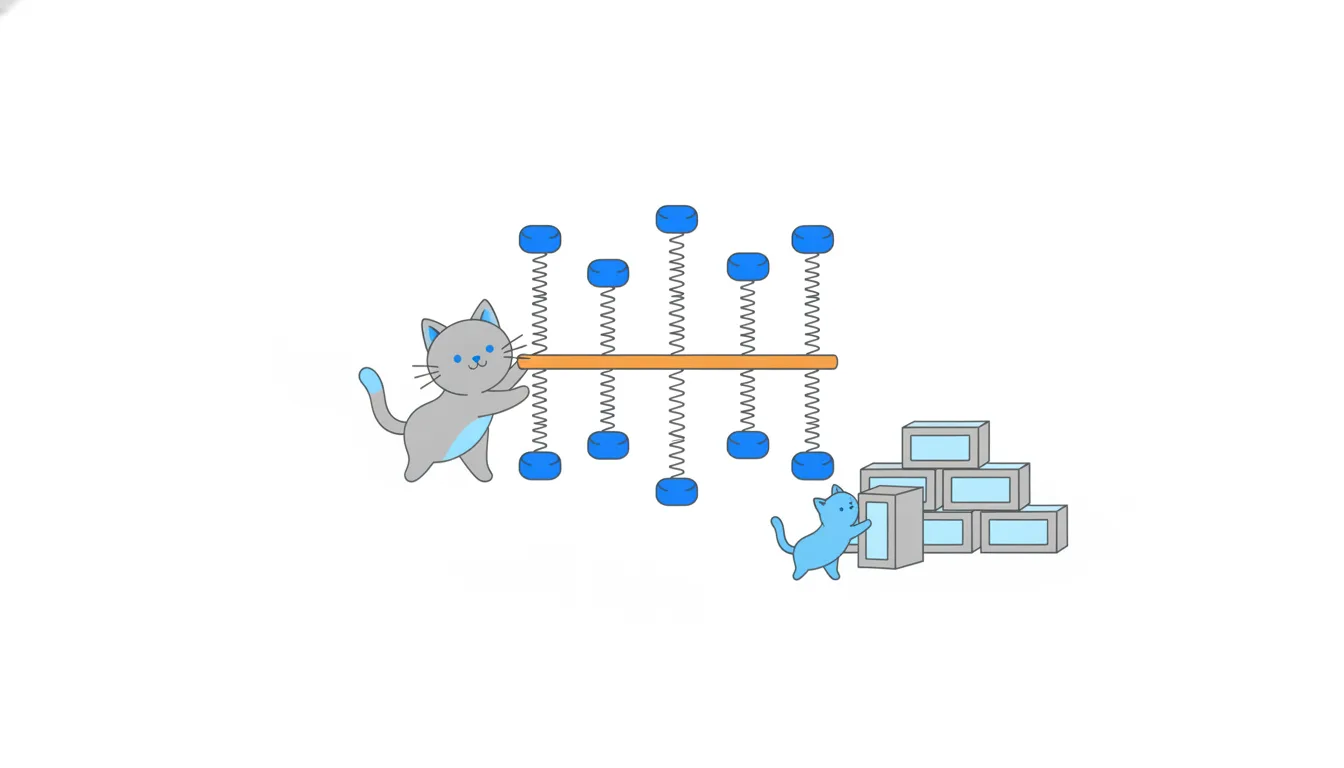
Why square? For the same two reasons as with variance: positive and negative gaps can't cancel, and a big miss costs much more than a small one, so the line can't ignore any dot that is far off.
A neat consequence: when the line has an intercept, its residuals always sum to exactly zero. If they didn't, you could shift the line up or down and reduce the squared total, so it wouldn't be the least-squares line. This holds for any least-squares fit, good or bad. A zero sum tells you the misses balance, not that they are small.
- Do“The residuals sum to zero, so over- and under-predictions balance out.”
- Don't“The residuals sum to zero, so the line fits perfectly.”
Every least-squares line with an intercept has this property.
Computing the slope
The least-squares slope reuses the sums you already met for r:
b1 = Σ(x − x̄)(y − ȳ) / Σ(x − x̄)²
The numerator is the sum of deviation products; the denominator is the sum of squared deviations of x only. For CatChow's ten weeks:
Dataset · 10 rows
CatChow weekly ad spend and orders from ads
The same ten weeks of ad spend and orders from the correlation lesson, now used to fit a line.
First 5 of 10 rows
b1 = 12,460 / 231,000 ≈ 0.0539 orders per dollar.
A slope per single dollar is hard to picture, so scale it to a step that matters: 0.0539 × 100 ≈ 5.39 orders per extra $100 of weekly spend. In a spreadsheet, SLOPE(orders range, spend range) gives the same number; note that the outcome comes first.
The slope carries units: orders per dollar. Unlike r, it changes when you change units: in orders per hryvnia it would be smaller by the exchange rate. Its sign always matches the sign of r, since both share the same numerator.
The classic slip is to divide by the wrong sum: using the squared deviations of y, or the square root from the r formula, gives a number that isn't a slope at all.
- Dob1 = 12,460 / 231,000 ≈ 0.0539 → about 5.39 orders per $100
- Don'tb1 = 12,460 / 749.6 ≈ 16.6 orders per dollar
Divides by the squared deviations of orders instead of spend.
The intercept and where it stops meaning anything
Once you have the slope, the intercept follows from one fact: the least-squares line always passes through the point of means (x̄, ȳ). So
b0 = ȳ − b1 × x̄ = 34.2 − 0.0539 × 470 ≈ 8.85.
Formula: The least-squares slope and intercept: the same numerator and denominator you computed for r, reused for the line's steepness. · shown above
Formally, b0 is the predicted value when x = 0: about 8.85 orders in a week with no ad spend. Sometimes that reading is useful. Here it needs a warning: CatChow never ran a week below $200, so x = 0 lies outside the data. The line was fitted to the $200–$700 stretch; below it, nobody knows whether orders from ads would level off, drop to zero or behave in some other way.
Dataset: CatChow weekly ad spend and orders from ads · shown above
Treat the intercept as a piece of the equation first and a business fact second. It's a meaningful baseline only when x = 0 is realistic and close to the data, like a price discount of 0% when you tested 0–20%.
In a spreadsheet, INTERCEPT(orders range, spend range) gives b0 directly.
- Do“b0 ≈ 8.85 is part of the equation; zero spend was never tested.”
- Don't“Turn ads off and we still keep 9 ad orders a week.”
Reads an extrapolated point as a measured baseline.
Making a prediction
With b0 and b1 in hand, a prediction is one line of arithmetic: plug x into ŷ = b0 + b1 × x.
For a week with $550 of spend:
ŷ = 8.85 + 0.0539 × 550 = 8.85 + 29.65 ≈ 38.5 orders.
Three habits keep predictions honest:
- multiply first, then add. Adding first, (8.85 + 0.0539) × 550, gives about 4,900 orders, an obvious nonsense that still turns up in spreadsheets;
- keep enough decimals in b1. Rounding 0.0539 to 0.05 shifts the prediction at $550 by about 2 orders; at larger x the error grows;
- stay inside the data. $550 sits well within $200–$700, so the prediction is an interpolation and fairly trustworthy. $900 would be an extrapolation.
A prediction is the line's best guess for a typical week with that spend, not a promise for a specific week. Week 7 had $550 too and brought 42 orders, about 3.5 above the line. Real weeks scatter around ŷ, and that scatter is what residuals and R² describe.
- Do8.85 + 0.0539 × 550 ≈ 38.5 orders
- Don't(8.85 + 0.0539) × 550 ≈ 4,897 orders
Adds before multiplying.
Reading residuals
A residual is what the line got wrong for one observation:
e = actual − predicted = y − ŷ.
The order matters. For week 4, with $400 of spend, the line predicts 8.85 + 0.0539 × 400 ≈ 30.41 orders; the week actually had 28, so e = 28 − 30.41 = −2.41. Negative means the line over-predicted; positive means it under-predicted. Swap the order and every sign flips, along with your story about which weeks did better than expected.
One residual is just one week's noise. The useful view is all of them together: plot residuals against x (or against ŷ).
- A shapeless band around zero is what you want: the line has captured the pattern and what's left is noise.
- A curve (negative at both ends, positive in the middle, or the reverse) means the true relationship bends, for example returns to ad spend that flatten at higher budgets. A straight line will be systematically wrong in places.
- A funnel that widens with x means predictions get less precise for big values.
A pattern in the residuals is the cue to change the model, not to trust it more.
- Doe = 28 − 30.41 = −2.41 (the line over-predicted)
- Don'te = 30.41 − 28 = +2.41, “week 4 beat the forecast”
Predicted minus actual flips the sign and the story.
R²: the share of variation the line explains
The coefficient of determination (R²) sums up the whole fit in one number.
Start with how much orders vary at all: the sum of squared deviations from their mean, SS_total = 749.6. Then see how much variation the line leaves unexplained: the sum of squared residuals, SS_residual ≈ 77.5. The rest is what the line accounts for:
R² = 1 − SS_residual / SS_total = 1 − 77.5 / 749.6 ≈ 0.90.
Read it as "about 90% of the week-to-week variation in orders lines up with ad spend". R² runs from 0 (the line does no better than predicting the mean every week) to 1 (every dot on the line). With a single predictor, R² is simply r²: 0.947² ≈ 0.90.
What R² doesn't tell you:
- whether the relationship is causal;
- whether the line is the right shape (a curve can still give a decent R²; check the residuals);
- how big the typical miss is in orders. A high R² can still leave misses of several orders a week.
And "good" depends on context: 0.3 can be useful for noisy customer behaviour.
- DoR² = 1 − 77.5 / 749.6 ≈ 0.90: the line explains about 90% of the variation.
- Don'tR² = 77.5 / 749.6 ≈ 0.10: “the line explains only 10%”.
That ratio is the unexplained share; R² is one minus it.
Four terms, one picture
Every simple regression output comes down to four pieces. Picture the scatter plot with the line drawn through it.
Chart: Ad spend vs orders from ads, 10 weeks · shown above
- Slope (b1): the tilt of the line. For CatChow, about 5.4 more orders for each extra $100 of weekly spend. Units: outcome per unit of predictor.
- Intercept (b0): where the line crosses x = 0, about 8.85 orders. Units: the outcome's. Meaningful only if x = 0 is near the data.
- Residual: the vertical gap between one dot and the line, actual minus predicted. One per observation; together they sum to zero.
- R²: one number for the whole line, the share of the variation in the outcome that the line accounts for. About 0.90 here.
The first two define the line; the last two describe how well the data fits it. A report that gives only b1 hides how noisy the relationship is; one that gives only R² hides the size of the effect. Give both, plus the range of x the line was fitted on.
A compact way to say it: "orders ≈ 8.85 + 5.4 per $100 of spend, R² = 0.90, fitted on $200–$700 a week".
- Do“+5.4 orders per $100, R² = 0.90, fitted on $200–$700 a week.”
- Don't“R² = 0.90, so each $100 brings 90% more orders.”
Mixes up the fit (R²) with the effect size (slope).
Three ways to misuse a good line
A line with R² = 0.90 is a good description of ten weeks. Trouble starts when it's asked to do more than that.
- Extrapolation. Every observed week had $200–$700 of spend. Plugging in $900 gives about 57 orders, but that number assumes the slope keeps going unchanged into territory nobody has measured. Ad returns often flatten as budgets grow, as cheaper audiences run out. Beyond the data, a prediction is a guess.
- Treating a good fit as a perfect one. R² = 0.90 leaves residuals of 2–4 orders in most weeks. A plan that needs every week to hit the forecast will be wrong most weeks.
- Reading the slope as a cause. The line describes how spend and orders moved together in the past. If spend rose mostly in busy seasons, part of the slope belongs to the season.
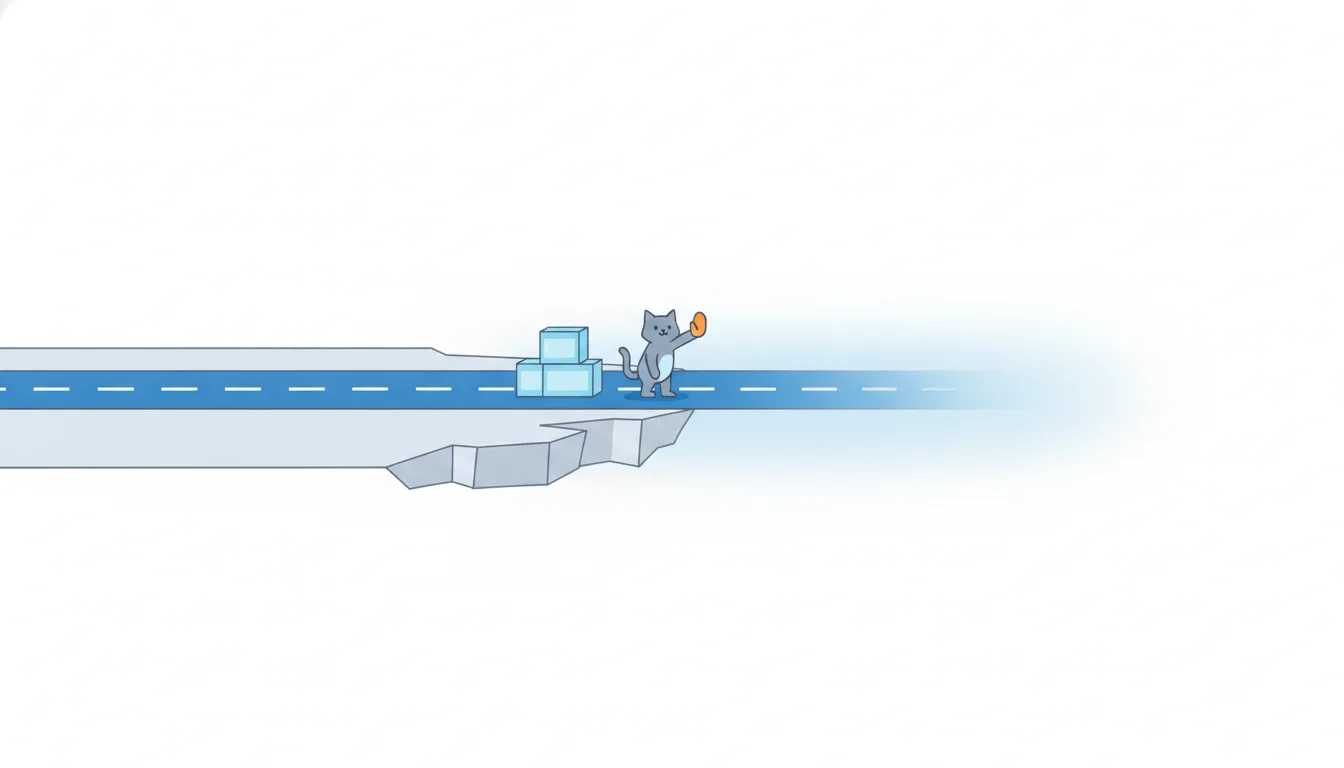
What isn't a risk: using a line just because R² is below 1. Real data is never perfect, and a line with a known error is still far better than a guess.
The safe way to plan bigger budgets is in steps: raise spend a little beyond the tested range, check actual orders against the line, then go further.
- Do“Test $750–$800 for a few weeks and compare actual orders with the line before going to $900.”
- Don't“The line says $900 gives 57 orders, so we lock that into the quarter plan.”
Commits to an extrapolation as if it were measured.
Ready to practise?
Answer the lesson's exercises and earn 250 points the first time you finish it.
Start the exercises